NeurIPS 2024
First Author
Oral · Top 1.8% accepted
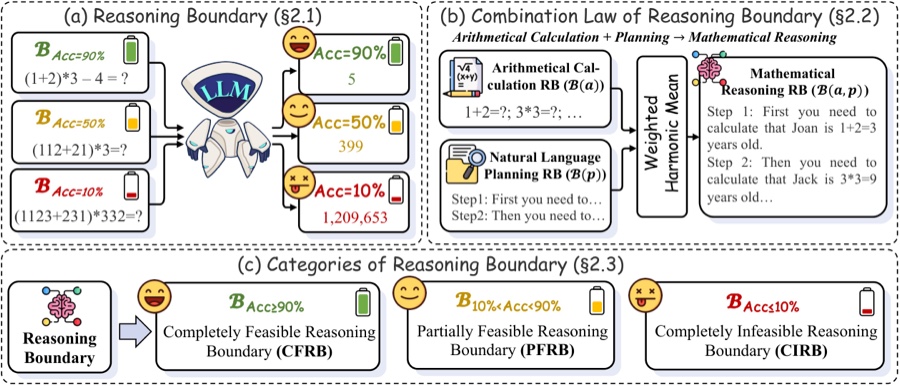
Unlocking the Capabilities of Thought: A Reasoning Boundary Framework to Quantify and Optimize Chain-of-Thought
A reasoning boundary framework that quantifies how far a model's chain-of-thought can go and optimizes it — turning an open-ended ability into a measurable quantity.
SCIS 2026
First Author
LMG Best Poster
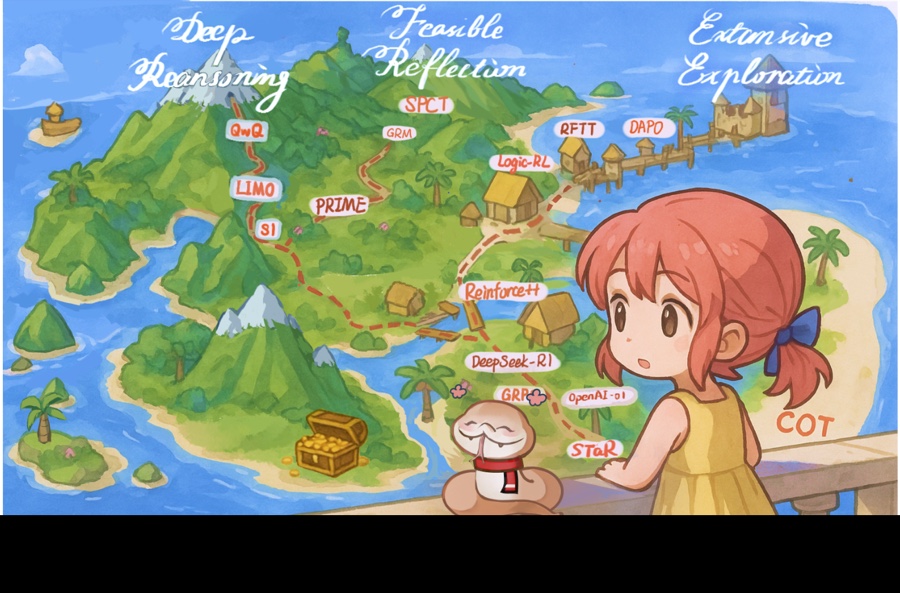
Towards Reasoning Era: A Survey of Long Chain-of-Thought for Reasoning Large Language Models
A systematic survey of long chain-of-thought reasoning — its landscape, training recipes and evaluation — with an accompanying paper list that has become a widely used reference for the community.
SCIS 2026
First Author
950+ papers surveyed
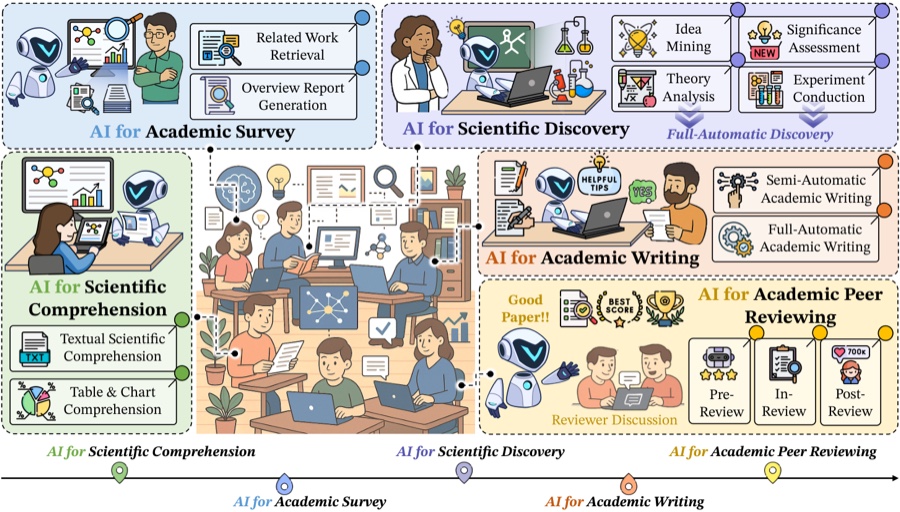
AI4Research: A Survey of Artificial Intelligence for Scientific Research
A data-centric review of AI for scientific research — organised around tasks, data and evaluation — released together with a living paper collection of 950+ papers.
ACL 2024
First Author
Oral · Top 2.3% submitted
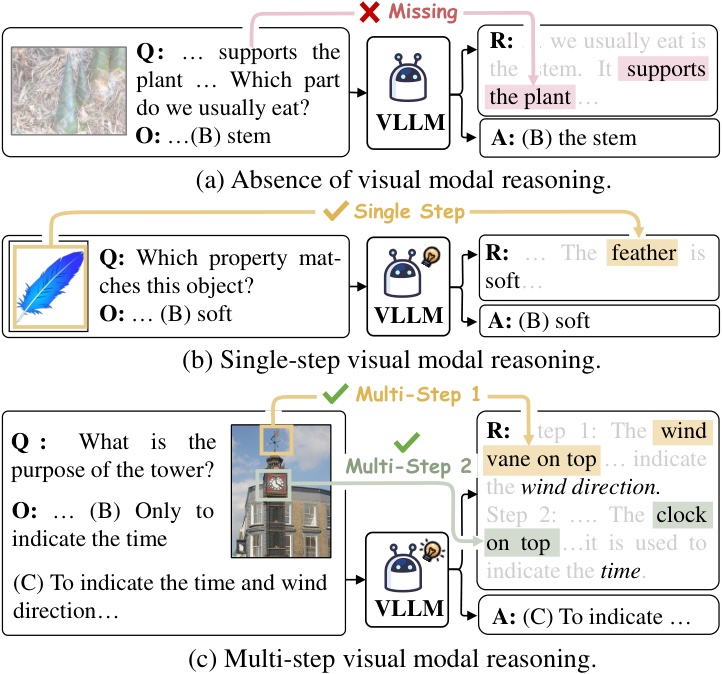
M3CoT: A Novel Benchmark for Multi-Domain Multi-step Multi-modal Chain-of-Thought
The first benchmark that pushes multi-modal chain-of-thought to multi-domain and multi-step visual reasoning — revealing that VLLMs still answer from textual shortcuts and leave a wide gap to human reasoning.